Technology
Meta Releases Muse Spark Open, an 816-Billion-Parameter Model That Runs on Two Mac Studios
Meta put an 816-billion-parameter model on a desk, provided the desk is two Mac Studios.
On October 15 the company released the weights for Muse Spark Open, which it calls the most capable U.S. open-weight model to date. It is natively multimodal, with 816 billion total parameters and 42 billion active, and a 1-million-token context window. Meta says it is built for coding and agentic work: long-horizon tasks, complex software engineering, multi-step reasoning. The weights are on Hugging Face, Amazon SageMaker AI, Google Cloud Model Garden, and Microsoft Foundry Models, under the Muse Model License. API access is live at Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter, and Together AI.
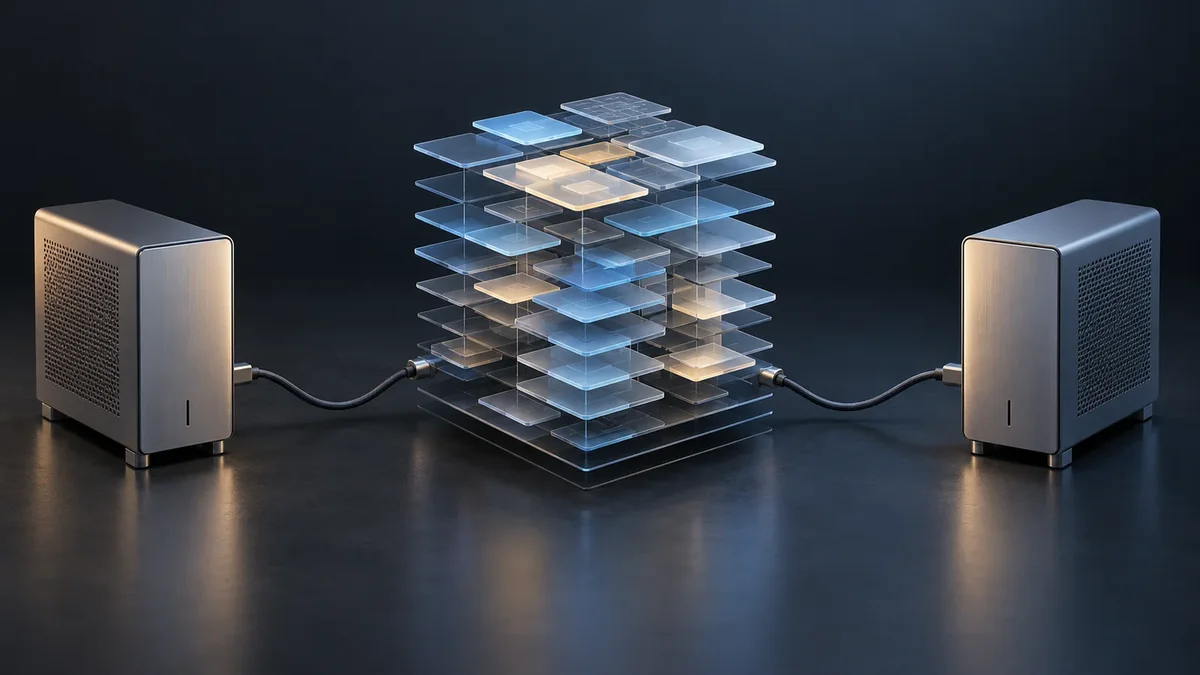
The desktop claim is the one that traveled. Meta says Muse Spark Open is the first model in its class to run on a desktop, using two Apple M5 Ultra Mac Studios and the latest MLX framework. Apple’s unified memory lets each M5 Ultra’s GPU use up to 512 GB. Two machines hold the model. Meta’s line is that the pair behaves like one supercomputer with a terabyte of unified memory, and that the chip’s 1.2 TB/s of memory bandwidth is fast enough to read the slice each token needs. Apple’s technical note is more precise: the model needs about 493 GB in a 4-bit format, and with inference overhead it does not fit on one Studio. It is split across machines linked by Thunderbolt. Four Studios generate more than 36 tokens per second. Two, with tensor parallelization, generate about 25.
What “Runs on a Mac Studio” Requires
The 512 GB M5 Ultra Studio is not fully on sale yet. Coverage notes it is due later this month. The 256 GB configuration already starts above $10,000. Two 512 GB units are a five-figure, possibly six-figure, purchase before the model is downloaded. “On your desktop” is accurate as a form factor. It is not a claim that a standard Mac can host this. A single Studio cannot. A laptop cannot.
Meta tested agentic workflows entirely on-device with Muse Code powered by the model: shipping real iOS changes to Ice Cubes, an open-source Mastodon client, including bug fixes, features, and a full build; and driving DaVinci Resolve end to end, reviewing footage frame by frame to pick moments and crop them vertical. Those are demonstrations on the dual-Studio setup, not benchmarks against a data-center GPU cluster. They are the proof Meta chose to show that the weights are usable without a cloud call.
How This Sits Next to Meta’s Other Models
Days earlier Meta released a closed frontier model, Muse Wonder, which it said matched leading closed systems on its own tests. Spark Open is the open-weight sibling, with additional safety post-training so it is more robust as a standalone model without system guardrails. PyTorch’s note says it shares a base with Muse Spark 1.3 and that TorchTitan now has a definition for fine-tuning it, including multi-turn supervised fine-tuning, LoRA, and reinforcement learning. The open release also ships custom Helion GPU kernels in SGLang, with reported kernel speedups on Nvidia and AMD and a small end-to-end gain on AMD MI350.
Alexandr Wang called it the most capable U.S. open-weight model to date and said it rivals, and in some cases outperforms, Chinese open equivalents. That is a positioning claim against DeepSeek-class models, not a published head-to-head table in the launch post. The license has limited commercial terms that let many developers use it free. “Open-weight” here means the weights are downloadable under that license, not that every use is unrestricted.
Why the Apple Partnership Matters
Meta and Apple do not usually ship a model together. MLX is Apple’s array framework for unified memory. Optimizing an 816-billion-parameter sparse model for two Studios is a joint engineering result: Meta’s weights, Apple’s memory architecture and framework, Thunderbolt between the boxes. John Ternus noted the work. For Apple it is a reason to buy the high-memory Studio when it arrives. For Meta it is a distribution channel that does not depend on a cloud provider’s GPU queue. For a developer who already owns or will own two maxed Studios, it is a local agent that does not send code off-machine.
The speed numbers — mid-20s to mid-30s tokens per second — are interactive for code and short agent steps, slow for long generation compared with a served GPU. Local is the point. The model stays on the Thunderbolt pair.
What to Watch
When the 512 GB M5 Ultra Studio actually ships, and at what price.
Independent speed tests against Meta’s 25-and-36-tokens-per-second figures.
Whether the Muse Model License blocks the uses developers most want.
Comparisons with Chinese open models on coding and agent benchmarks, which the launch post asserts but does not fully table.
Uptake on Hugging Face versus the API providers.
Meta released Muse Spark Open, an 816-billion-parameter open-weight model with 42 billion active and a million-token window, and said it runs on two M5 Ultra Mac Studios. The weights are downloadable. The hardware that holds them is expensive and not fully available yet. The claim is that a desktop — two of them, linked — can now run a model Meta ranks as the strongest U.S. open-weight release.
Comments (0)
Please log in to comment
No comments yet. Be the first!